
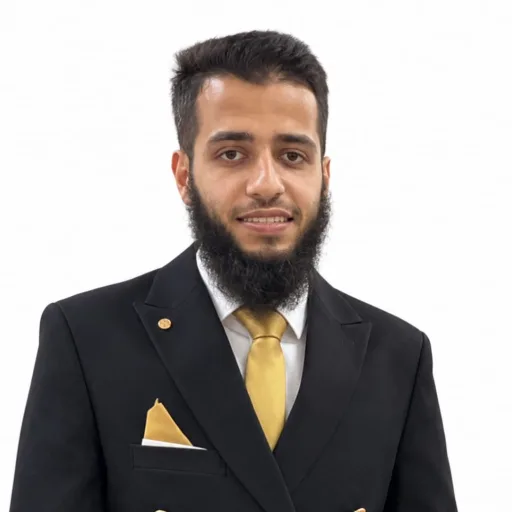
Anas Al Kasaba
Artificial Intelligence Specialist
Python
Data Pipeline & Feature Engineering: 6/10
MLOps & Deployment: 5/10
Computational Efficiency: 5/10
Active 2 days ago
Download CVCV
Overview
Technical skills
Projects
Timeline
Roles
Overview
A practical LLM and multimodal engineer (senior-level estimate) who builds end-to-end RAG and classroom CV inference pipelines with Streamlit frontends. The strongest proven skill is integrating retrieval-augmented workflows and local LLM calls with concrete code in initialize_rag and generate_answer in Scholarship-AI-Assistant/app.py. There is limited evidence of custom research or distributed training, formal experiment tracking, or production-grade MLOps such as CI/CD and model versioning in public code.
Phone
Technical skills
Languages
1
Python
AI/ML
20
Mistral
NumPy
Pandas
YOLO
OpenCV
Scikit-learn
XGBoost
MediaPipe
Streamlit
Ultralytics
LLM
Sentence-Transformers
Transformers
PyTorch
Embeddings
Mistral SDK
RAG
Qwen
Vision
Ollama
Analytics
3
Plotly
Matplotlib
Power BI
DevOps
3
Rest API
GitHub
Git
Other
4
Requests
Chroma
Machine Learning
Multimodal AI
Projects

Developed a machine learning regression model to predict calories burned from personal and exercise-related features. Trained and compared Random Forest against Linear Regression and evaluated results using MAE, MSE, and R². Delivered an interactive Streamlit app to test the model predictions.
Built a PDF-based scholarship question-answering assistant with a Streamlit chat UI. Implemented section-aware context selection using semantic retrieval with Sentence Transformers and ChromaDB. Connected a locally hosted Qwen model via Ollama to generate answers from the retrieved document context.
Contributed to a team graduation project for analyzing classroom behavior and identifying student focus. Integrated wearable-sensor stress classification and academic performance risk prediction into an AI workflow. Supported the Streamlit dashboard and weekly AI-generated reporting features.
Timeline

Al Balqa Applied University
Bachelor's Degree ·
الذكاء الاصطناعي والروبوتات
AI & Data Analytics Trainee (Summer Training Program)
·
Junior
App Trainers
·
Internship
Completed a short training program focused on data analysis and preprocessing in Python. Applied machine learning algorithms to practical datasets and built interactive Streamlit applications to present model predictions. Produced data visualizations and reporting outputs using Power BI.
Python
Streamlit
Power BI
Senior AI/ML Engineer
Confidence: Medium LLM Engineer
A practical LLM and multimodal engineer (senior-level estimate) who builds end-to-end RAG and classroom CV inference pipelines with Streamlit frontends. The strongest proven skill is integrating retrieval-augmented workflows and local LLM calls with concrete code in initialize_rag and generate_answer in Scholarship-AI-Assistant/app.py. There is limited evidence of custom research or distributed training, formal experiment tracking, or production-grade MLOps such as CI/CD and model versioning in public code.
Model Architecture & Training
3/10
How well models are designed and trained
Model training and architecture work is present but mostly uses standard libraries and pretrained models; there are training scripts and classical ML model usage but no custom training loops or novel architectures.
Evidence
AI-EduVision/training/prefor_module/train.py: XGBClassifier training and GridSearchCV usage
Calories-Burned-Prediction/task2.ipynb: RandomForest and LinearRegression training and joblib.dump
Data Pipeline & Feature Engineering
6/10
How data is prepared for models
Clear, practical data pipelines and parsing logic with validation and fallback; includes PDF chunking for RAG, CSV validation, filename parsing and merging strategies.
Evidence
Scholarship-AI-Assistant/app.py: initialize_rag - PDF extraction, chunking, overlap and embedding creation
AI-EduVision/deployment/utils.py: read_watch_csv and read_academic_csv with explicit required-column checks and normalization
AI-EduVision/deployment/utils.py: parse_session_filename - robust filename parsing for session metadata
Experimentation & Evaluation
4/10
How results are measured and tested
Basic evaluation and reporting artifacts exist (notebooks and YOLO validation helpers) but there is no experiment tracking or systematic reproducibility stack.
Evidence
Calories-Burned-Prediction/task2.ipynb: computed MAE/MSE/R2 comparisons and saved model artifact
AI-EduVision/deployment/camera/test_model.py: mode_val prints mAP, precision, recall and saves validation artifacts
MLOps & Deployment
5/10
How models are shipped to production
Deployment-focused code is present with Streamlit apps, model loading/caching, fallbacks and API calls to hosted models, but lacks CI/CD, model versioning or advanced monitoring.
Evidence
Calories-Burned-Prediction/app.py: Streamlit app loading joblib model and serving predictions
Scholarship-AI-Assistant/app.py: end-to-end RAG + local LLM call to Ollama endpoint
AI-EduVision/deployment/app.py and utils.py: model caching (load_camera_models), fallback behavior and Mistral API report generation
Computational Efficiency
5/10
How efficiently computing resources are used
Practical efficiency measures are implemented for inference: frame sampling, resizing, model caching and tracker use, showing awareness of runtime constraints.
Evidence
AI-EduVision/deployment/utils.py: process_video uses process_every sampling and resize to 720x480
AI-EduVision/deployment/utils.py: load_camera_models caches loaded models to avoid repeated initialization
AI-EduVision/deployment/camera/main.py: use of model_persons.track with tracker and cap buffer tuning
Research Depth & Innovation
2/10
Depth of research and new ideas
There is limited research-level innovation; code applies established libraries and techniques rather than novel algorithms or reproduced papers.
Evidence
AI-EduVision/deployment/utils.py: head-pose extraction using MediaPipe facial transformation matrices
AI-EduVision/deployment/camera/test_model.py: helper functions for model info and validation but no new algorithms
Expertise
RAG· Middle
Conversational AI & Chatbots· Middle
Technologies
 Qwen· since 2026
 Sentence-Transformers
 Multimodal AI
 Mistral SDK
 Ollama· since 2026
 Mistral
 Transformers
 Git· since 2026
 PyTorch
 LLM
 Ultralytics
 GitHub· since 2026
Machine Learning
Computer Vision· mentioned only
Multimodal AI· mentioned only
Ollama· mentioned only
RAG· mentioned only
Transformers· mentioned only
Vision· mentioned only
XGBoost· mentioned only
Recommendations
- Develop RAG-based document assistants and secure local LLM integrations where prompt templates, embeddings, and vector DB operations are core features.
- Build multimodal inference pipelines that fuse camera-based CV outputs with wearable sensor CSVs and provide robust fallbacks and data validation.
- Prototype production-ready inference services with model versioning, CI/CD, monitoring and secrets management rather than ad-hoc API keys in UI flow.
- Implement experiment tracking (W&B or MLflow) and reproducible training pipelines for the XGBoost/YOLO parts to make evaluation and iteration rigorous
Repositories
The developer's experience in this domain has been verified based on AI analysis of the following repositories:
Senior Data Scientist
Confidence: High ML Practitioner
Real-time computer vision and ML practitioner (senior-level, ~4.0) focused on end-to-end prototypes for education use cases with strong applied engineering in CV and interactive dashboards. The strongest proven skill is building integrated CV pipelines and teacher-facing analytics, as shown by the AI-EduVision camera processing, utils.py data-fusion and the Streamlit dashboards (deployment/app.py and deployment/utils.py). There is limited evidence of production hardening for large-scale data engineering, formal statistical rigor, automated testing, or data-versioned reproducible ML pipelines.
Statistical Rigor
2/10
Correct use of statistics
Basic model evaluation metrics are present but there is little evidence of rigorous statistical assumption checks, uncertainty quantification, or causal reasoning.
Evidence
Calories-Burned-Prediction/task2.ipynb: model metrics (MAE/MSE/R2) reported without assumption tests
AI-EduVision/deployment/generate_mistral_report: summary statistics used for reporting rather than formal statistical analysis
Data Wrangling & Cleaning
6/10
Preparing and cleaning data
Robust, defensive data handling is visible: schema checks, column normalization, fallback logic, filename parsing and merge fallbacks show practical data-wrangling experience.
Evidence
AI-EduVision/deployment/utils.py: read_watch_csv and read_academic_csv with explicit column checks and normalization
AI-EduVision/deployment/utils.py: parse_session_filename with normalization and multiple parsing strategies
AI-EduVision/deployment/utils.py: fuse_data with primary/secondary merge strategies and sensible defaults
Exploratory Analysis & Visualization
5/10
Exploring and visualizing data
Multiple interactive dashboards and charts are implemented and include some narrative/interpretation, but exploratory analysis in notebooks is minimal and often template-like.
Evidence
AI-EduVision/deployment/camera/dashboard.py: Plotly visualizations and teacher-facing dashboards with computed metrics
AI-EduVision/deployment/app.py: student profile tables and combined subject summaries with written notes
Predictive Modeling
5/10
Building models that predict
Predictive modeling and ML training are present (Random Forest, XGBoost, GridSearchCV), with model saving and basic evaluation, but advanced evaluation (robust CV strategies, leakage checks across modalities) and calibration are not strongly evidenced.
Evidence
Calories-Burned-Prediction/task2.ipynb: RandomForest training, evaluation and joblib.dump(model.pkl)
AI-EduVision/training/prefor_module/train.py: XGBClassifier with GridSearchCV and classification_report
Business Insight & Impact
5/10
Turning analysis into business value
Work is explicitly tied to an education use case and the apps produce teacher-friendly outputs and recommendations, demonstrating awareness of downstream impact but limited operationalization of business constraints or risk-cost trade-offs.
Evidence
AI-EduVision/deployment/generate_mistral_report: constructs teacher-oriented weekly reports and concrete recommendations
AI-EduVision/deployment/app.py: UI sections mapping analytics to teacher actions and warnings
Reproducibility & Notebook Hygiene
4/10
Clean, repeatable analysis
Reproducibility basics exist (requirements.txt, model artifacts saved, Streamlit caching), but there is no evidence of CI/CD, data versioning (DVC), containerization, or systematic notebook-to-module refactoring.
Evidence
Calories-Burned-Prediction/requirements.txt and joblib.dump in task2.ipynb
Scholarship-AI-Assistant/app.py: use of @st.cache_resource for model loading
Expertise
Data Science· Middle
Industries
Education· Middle
Technologies
Vision
 Chroma
 OpenCV
 YOLO
 XGBoost· since 2026
 Embeddings
 Scikit-learn· since 2026
Plotly
 Pandas
 NumPy
 RAG
 MediaPipe
 Streamlit
Computer Vision· mentioned only
Multimodal AI· mentioned only
Ollama· mentioned only
Transformers· mentioned only
Recommendations
- Productionize the CV pipeline: add containerization (Docker), a lightweight CI pipeline, and instructions for deployment (including model artifact management) so the system can run reproducibly in staging/production.
- Add systematic evaluation and unit/integration tests: validation scripts, reproducible randomness (pinned seeds), end-to-end tests for process_video and fuse_data, and CI checks for data schema changes.
- Improve statistical rigor and model monitoring: add cross-validation pipelines, leakage checks across sessions, calibration and uncertainty quantification, plus a simple monitoring dashboard for model drift and data quality.
- Introduce data/version control and dataset provenance (DVC or equivalent) and clearly separate raw/processed data directories to enable reproducible retraining and auditing.
Repositories
The developer's experience in this domain has been verified based on AI analysis of the following repositories:
Middle Backend Developer
Confidence: Medium Generalist
Backend Python engineer (middle-level) focused on building AI-driven tools and computer-vision assisted education tooling. The strongest proven skill is building end-to-end AI pipelines and integrations, evidenced by the RAG pipeline and local LLM integration implemented in the app.py RAG flow and embedding collection logic. There is limited evidence of production-grade backend practices such as schema migration history, formal test suites, distributed system design or advanced observability.
API Design
2/10
How well APIs are designed
Minimal API design conventions; external HTTP calls exist with timeouts but no versioning, idempotency, standardized error contract or documented API surface.
Evidence
Scholarship-AI-Assistant/app.py: generate_answer uses requests.post to local Ollama endpoint with a prompt and timeout
AI-EduVision/deployment/utils.py: generate_mistral_report posts to Mistral API with Authorization header and timeout
Data Layer & Database
3/10
Working with databases
Work with a vector DB and careful CSV validation and merge logic; no evidence of migration history, transactional boundaries or tuned SQL queries.
Evidence
Scholarship-AI-Assistant/app.py: initialize_rag creates a ChromaDB collection and adds embeddings
AI-EduVision/deployment/utils.py: read_watch_csv, read_academic_csv validate required columns; fuse_data implements merge with fallback key strategy
Scalability & Performance
3/10
Handling load and speed
Practical performance choices exist (frame sampling, model caching, st.cache_resource) but there are no system-level scaling patterns like queues, rate limiting, connection pooling or load-test results.
Evidence
AI-EduVision/deployment/utils.py: process_video uses process_every to sample frames and caches loaded models in _camera_models_cache
Scholarship-AI-Assistant/app.py: initialize_rag is decorated with @st.cache_resource to avoid reloading models and embeddings
System Architecture
3/10
Overall system structure
Reasonable module separation for UI, utilities and model code; overall design remains monolithic and oriented to single-host/Streamlit usage without service decomposition or inter-service contracts.
Evidence
AI-EduVision/deployment/app.py: orchestration layer that coordinates uploads, processing and uses utils functions
AI-EduVision/deployment/utils.py: encapsulates video processing, CSV parsing and data fusion as a utility module
Security & Auth
3/10
Protecting data and access
Basic security awareness: env var usage for API key, CSV input validation and HTTP timeouts; lacks evidence of token lifecycle, RBAC, secrets management, or dependency audit tooling.
Evidence
AI-EduVision/deployment/app.py: reads MISTRAL_API_KEY from environment and exposes it to session state
AI-EduVision/deployment/utils.py: generate_mistral_report sets Authorization header and uses request timeouts
Reliability & Observability
3/10
Stability and monitoring
Pragmatic reliability practices such as try/except handling, explicit fallback results and user-facing error messages are present; limited structured logging, retries with backoff, metrics or alerting.
Evidence
Scholarship-AI-Assistant/app.py: try/except around initialize_rag and explicit handling for requests.exceptions.Timeout
AI-EduVision/deployment/utils.py: load_camera_models returns (None, error) and process_video returns deterministic fallback results when models or video are unavailable
Expertise
Backend AI & LLM· Middle
Databases & Vector Storage· Middle
Python· Middle
Industries
Education· Middle
Artificial Intelligence· Middle
Technologies
 Python· since 2026 · Senior
 Rest API
 Requests
Recommendations
- Build RAG prototypes and local-LLM integrations for knowledge-heavy assistants and internal tooling.
- Develop computer-vision inference pipelines and data-fusion utilities for edge-to-dashboard workflows (video processing, head-pose, seat-mapping).
- Implement Streamlit-based teacher dashboards and rapid ML/analytics prototypes that combine camera and sensor data.
- Harden production readiness by adding CI, automated tests, structured logging/metrics and deployment/serving patterns
Repositories
The developer's experience in this domain has been verified based on AI analysis of the following repositories: